Gemi
Personal room-assistant prototype using Gemini Live for lights, music, and an iPad display.
Spring 2025 · AI tooling · Completed personal project
Stack
Stack: SwiftUI · Gemini Live · Gemini 2.0 Flash Thinking · Llama 3.2:3b · Fast Whisper · Orpheus TTS · Spotipy · ISY REST · Random Forest
No wake word. This personal prototype sent voice input through Gemini Live for external AI processing; the loop still had to feel quick enough for conversation.
Log
Spring 2025 — opening
Google Home Mini used to flip the lights when I asked. Family stopped paying for the subscription, the bridge to our Universal Devices ISY went silent, and the room forgot how to listen.
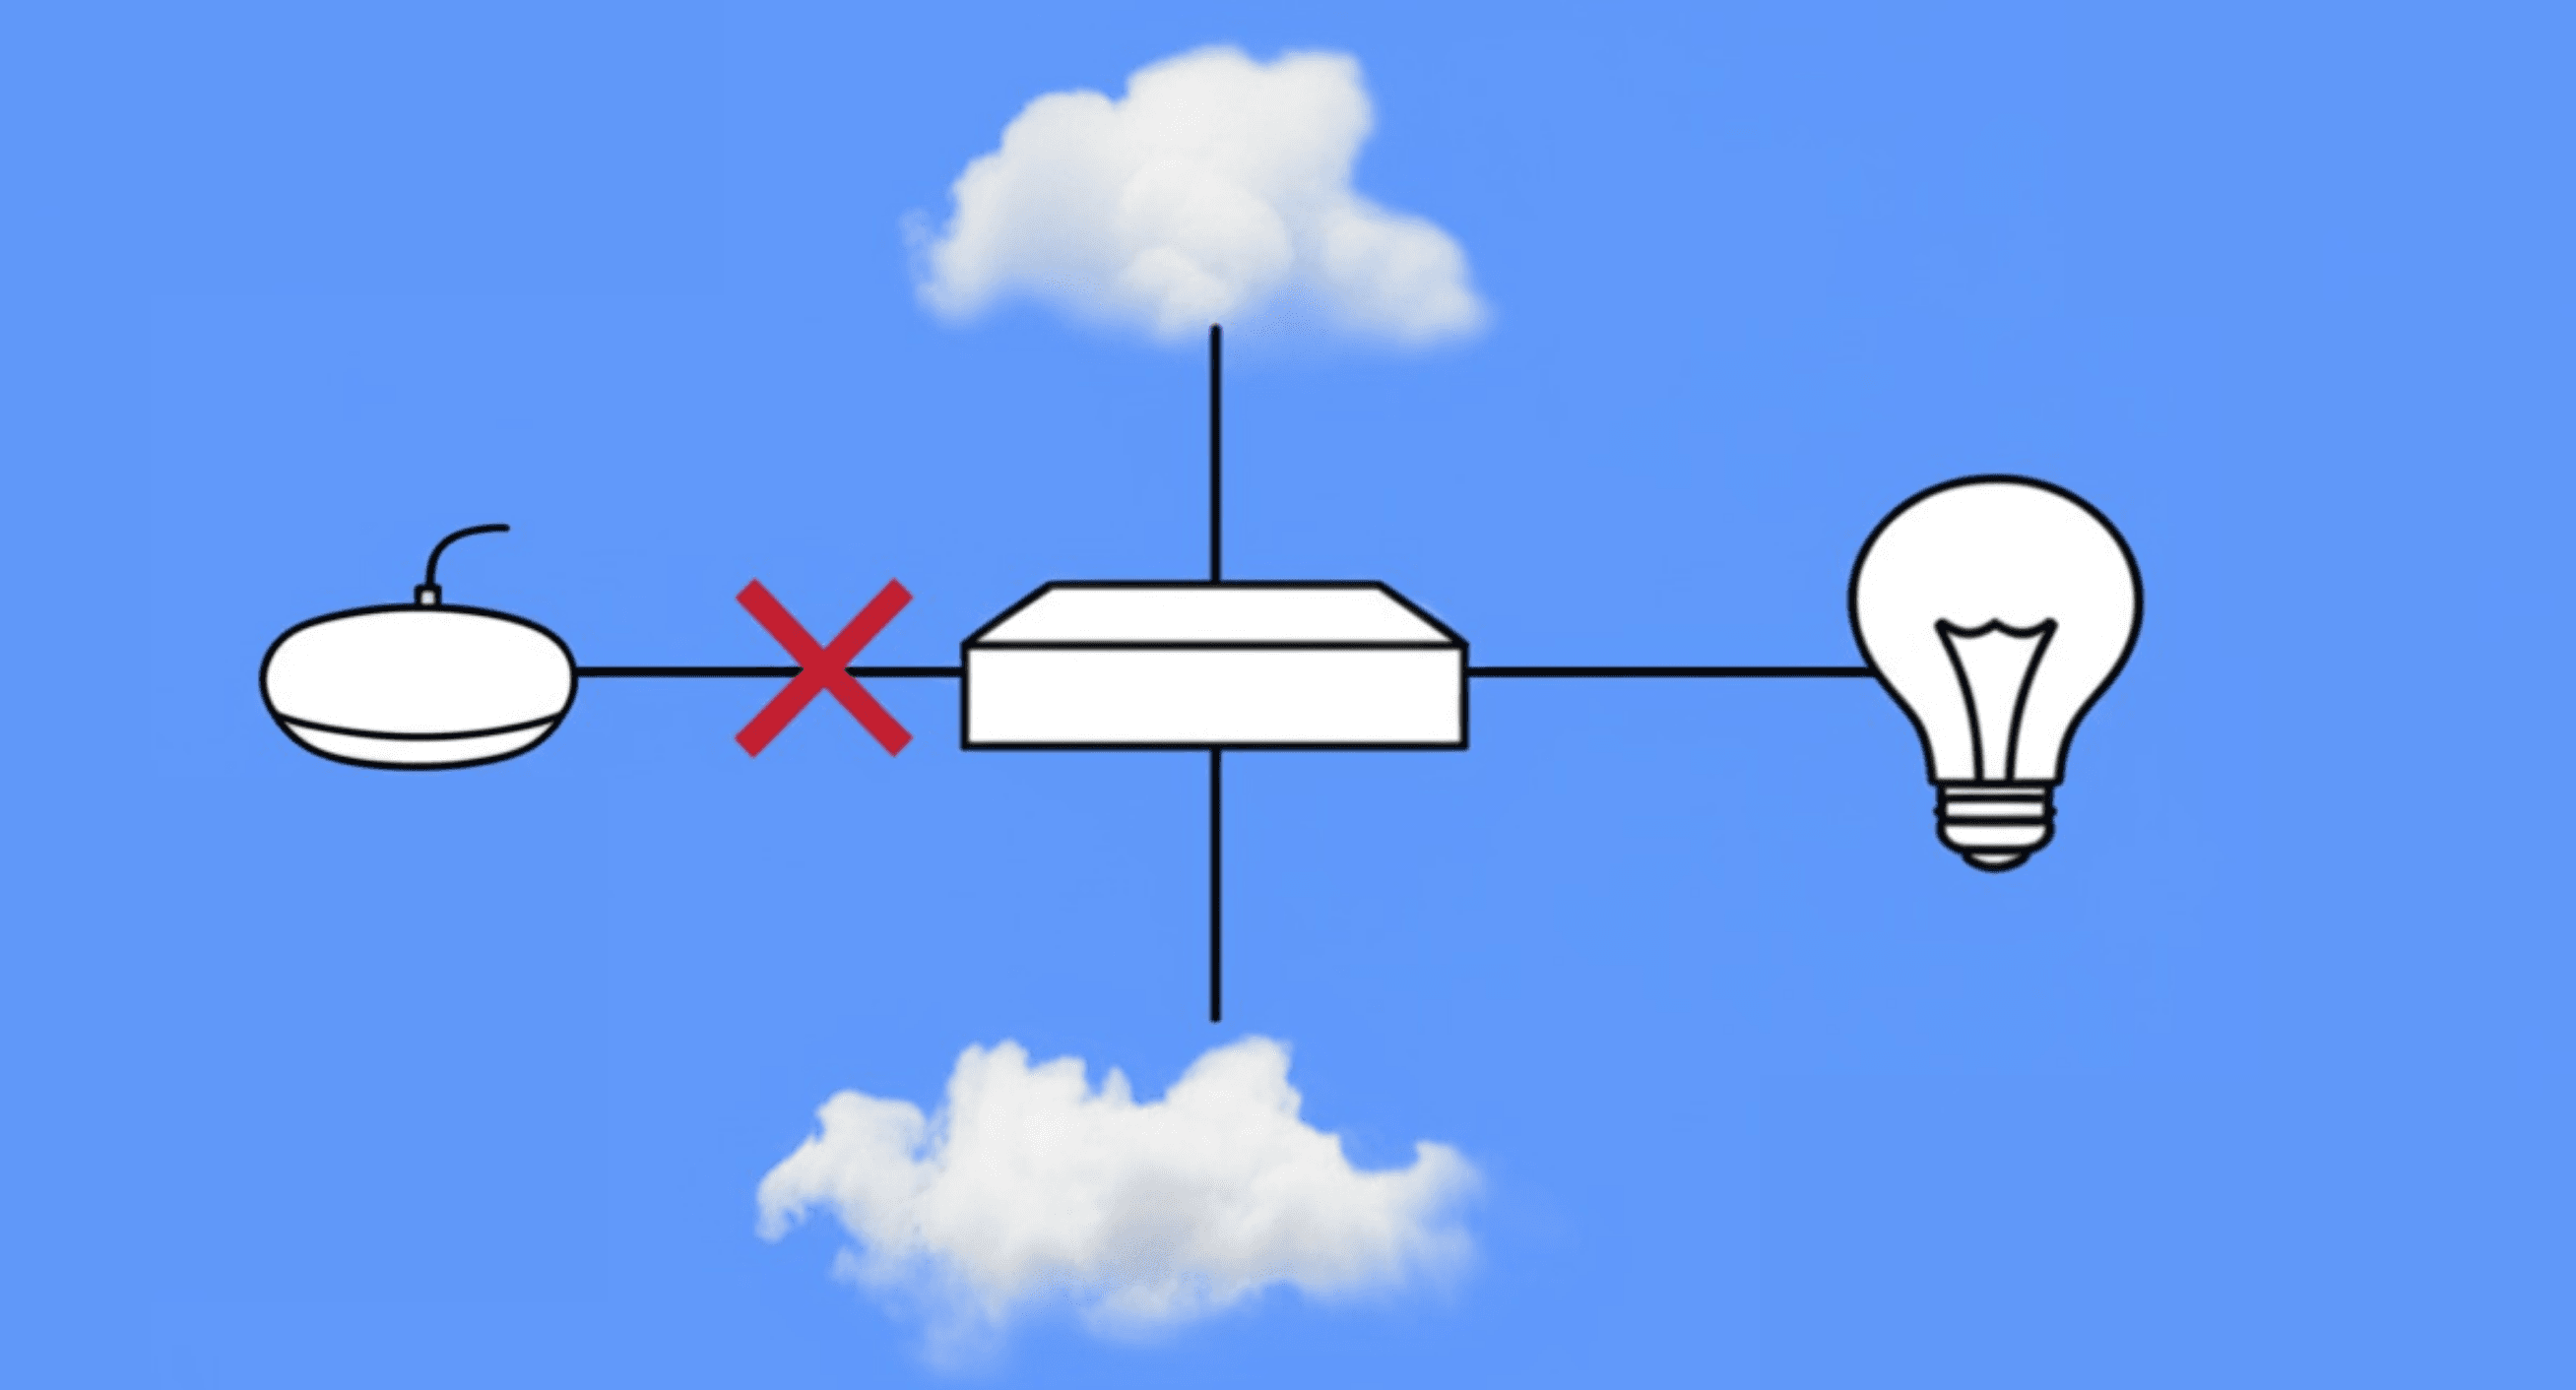
The link that died. What I want
No keyword. Automatic recognition — is it being spoken to, how many commands. Lights, music, and a clean iPad on the wall as the surface.
The first pipeline
Streaming mic into speech-to-text, into an LLM, then out through two routes: function calls for the room and text-to-speech back to the user. Magic, but plumbed.
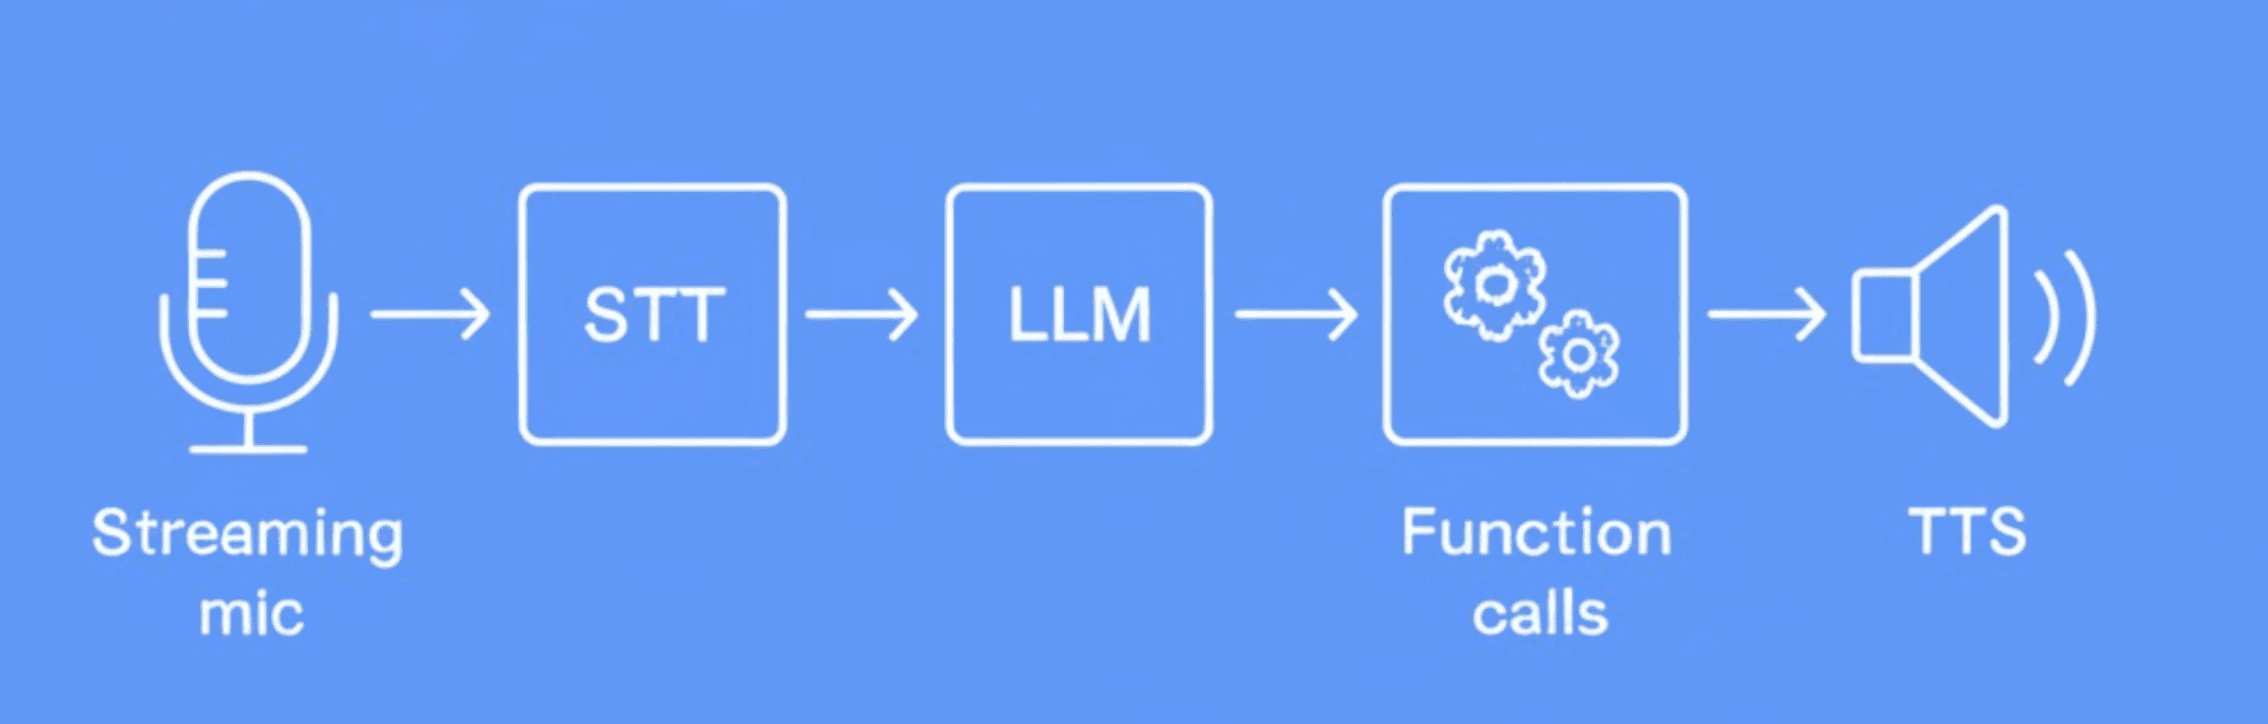
Mic in, function calls and voice out. Lights
The Universal Devices ISY exposes a REST API — get and set against an XML node tree. Could've wired the whole house, but went with what the assistant would actually need to reach: room, lamp, hallway, bathroom.
Spotify
PyChromecast first, since the old Google Homes already spoke that language — but it couldn't pick songs by name. Switched to Spotipy 2.25.1, OAuth'd into my account, and pointed playback at my speaker group.
Dual route
Latency was the gap between assistant and presence. Split voice activation into two parallel tracks — Llama 3.2:3b on the spoken-response track ("yeah, on it"), Gemini 2.0 Flash Thinking on the function-call track. The room could answer out loud while Gemini was still deciding what to actually do.
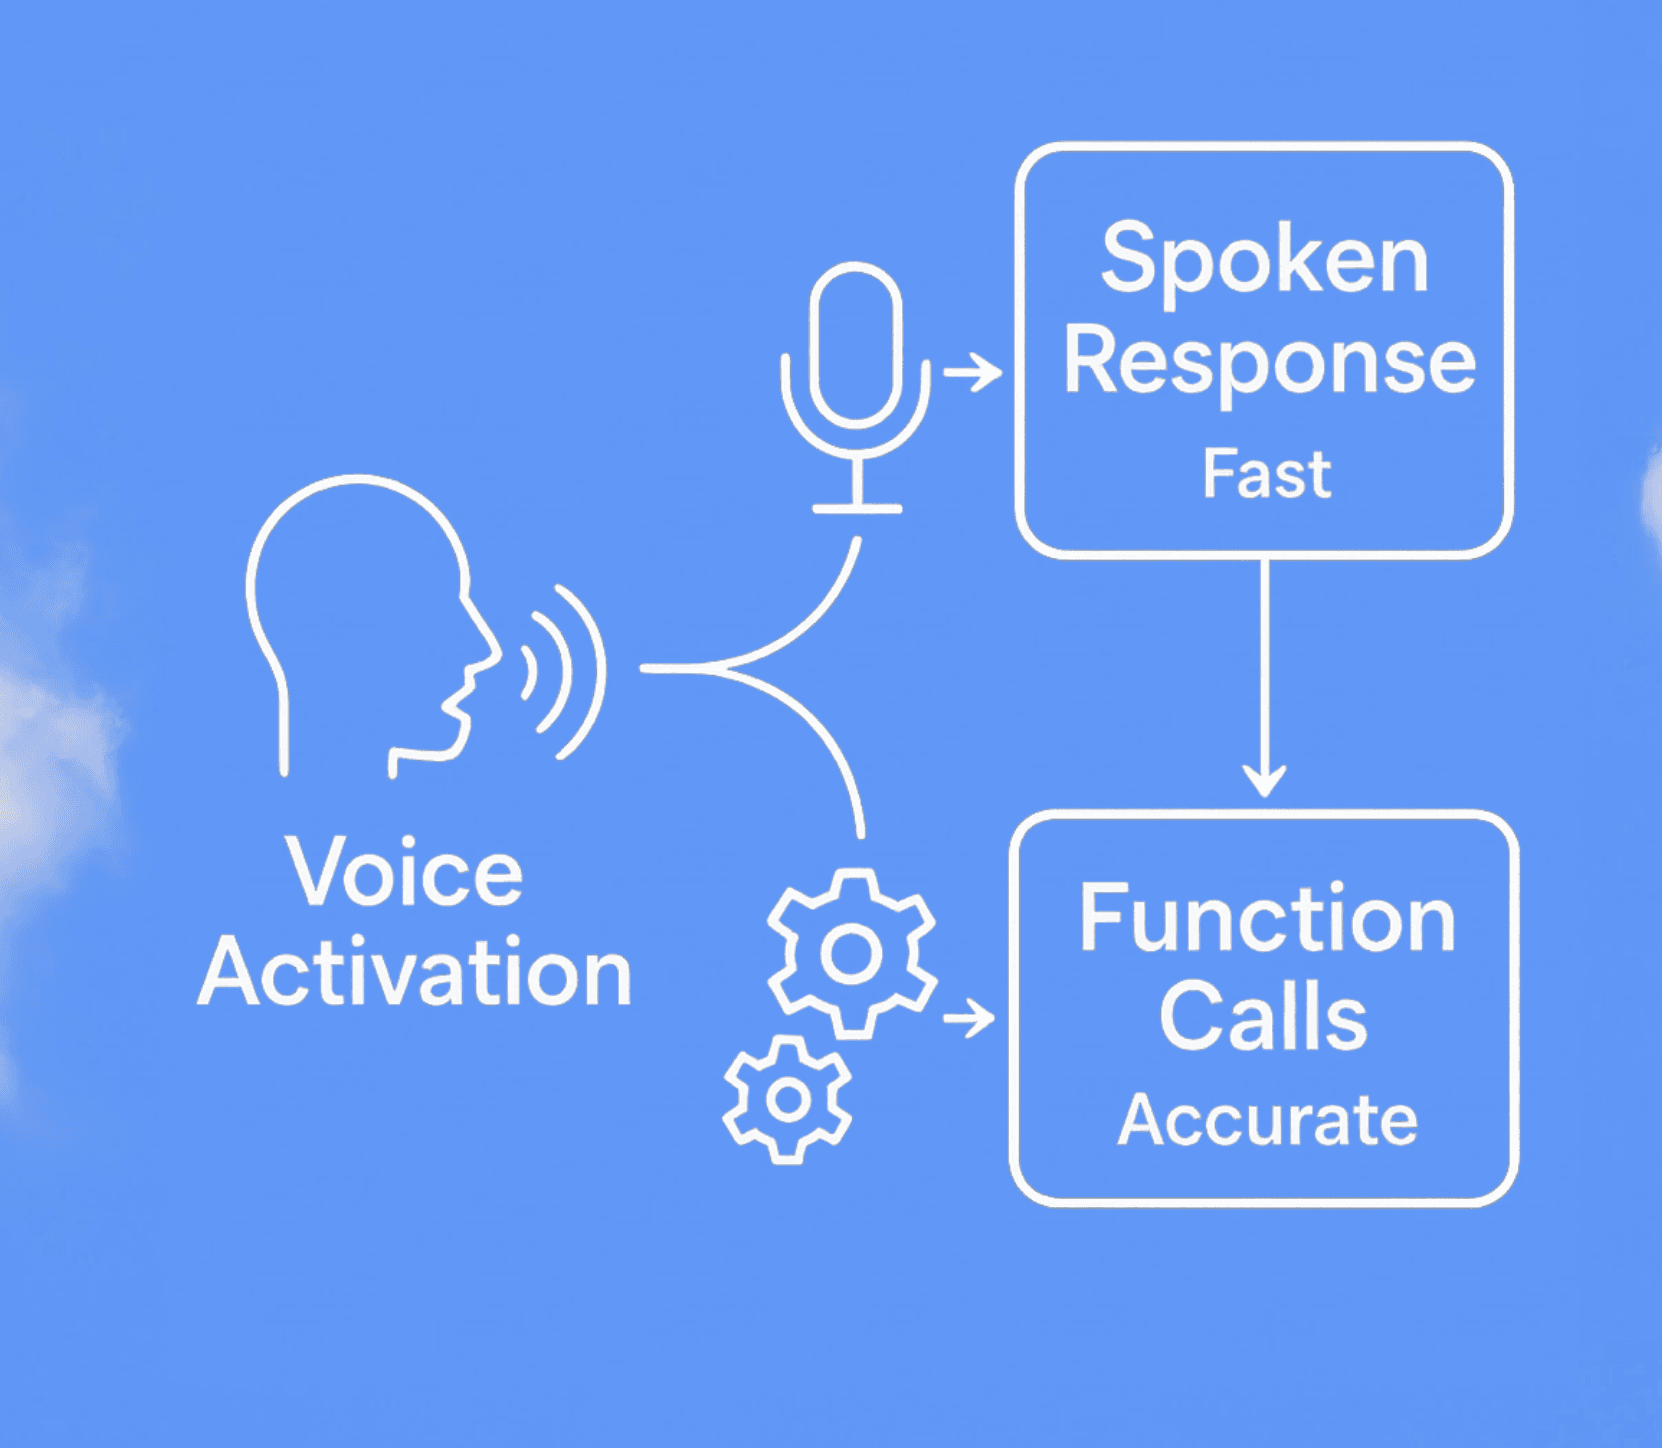
An acknowledgement track beside the room-action track. STT — Faster-Whisper
For the first pipeline, I used Faster-Whisper for speech-to-text before the language model. It handled the transcription leg of the mic-to-action-and-voice chain.
LLM — small voice, big brain
Llama 3.2:3b handled brief acknowledgments like "yeah, got it" while Gemini 2.0 Flash Thinking handled the room-action requests. The split let an acknowledgment start while an action was still being worked out.
TTS — Orpheus over Nari Dia
Tried Nari Dia 1.6B first — expressive, but too slow for a voice that's supposed to interrupt itself. Orpheus TTS gave back a balance, plus inline tags for laugh, chuckle, and breath that nudge it past flat-affect synthesis.
iPad as mirror
Inspired by Siri's redesign — the gradient border around the screen edge that pulses with whatever's being spoken. Mounted the iPad on the wall as a mirror with the live camera feed underneath, gradient on top, and a small dark debug terminal overlaid in the corner so I could watch what it was hearing.
Stereo Love
Demo from the iPad mounted on the wall, gradient border pulsing with the audio. "Can you turn off my hallway lights?" — hallway clicks off through the doorway. "And turn off my room lights too." — overhead goes dark. "Can you play Stereo Love on Spotify?" — Spotipy sends it to my speaker group, and Edward Maya fills the room.
Lamp off, live
End of the talk, no slide. Raised a hand: "Okay, turn off my lamp." The lamp behind me clicked off. Mic drop without the mic.
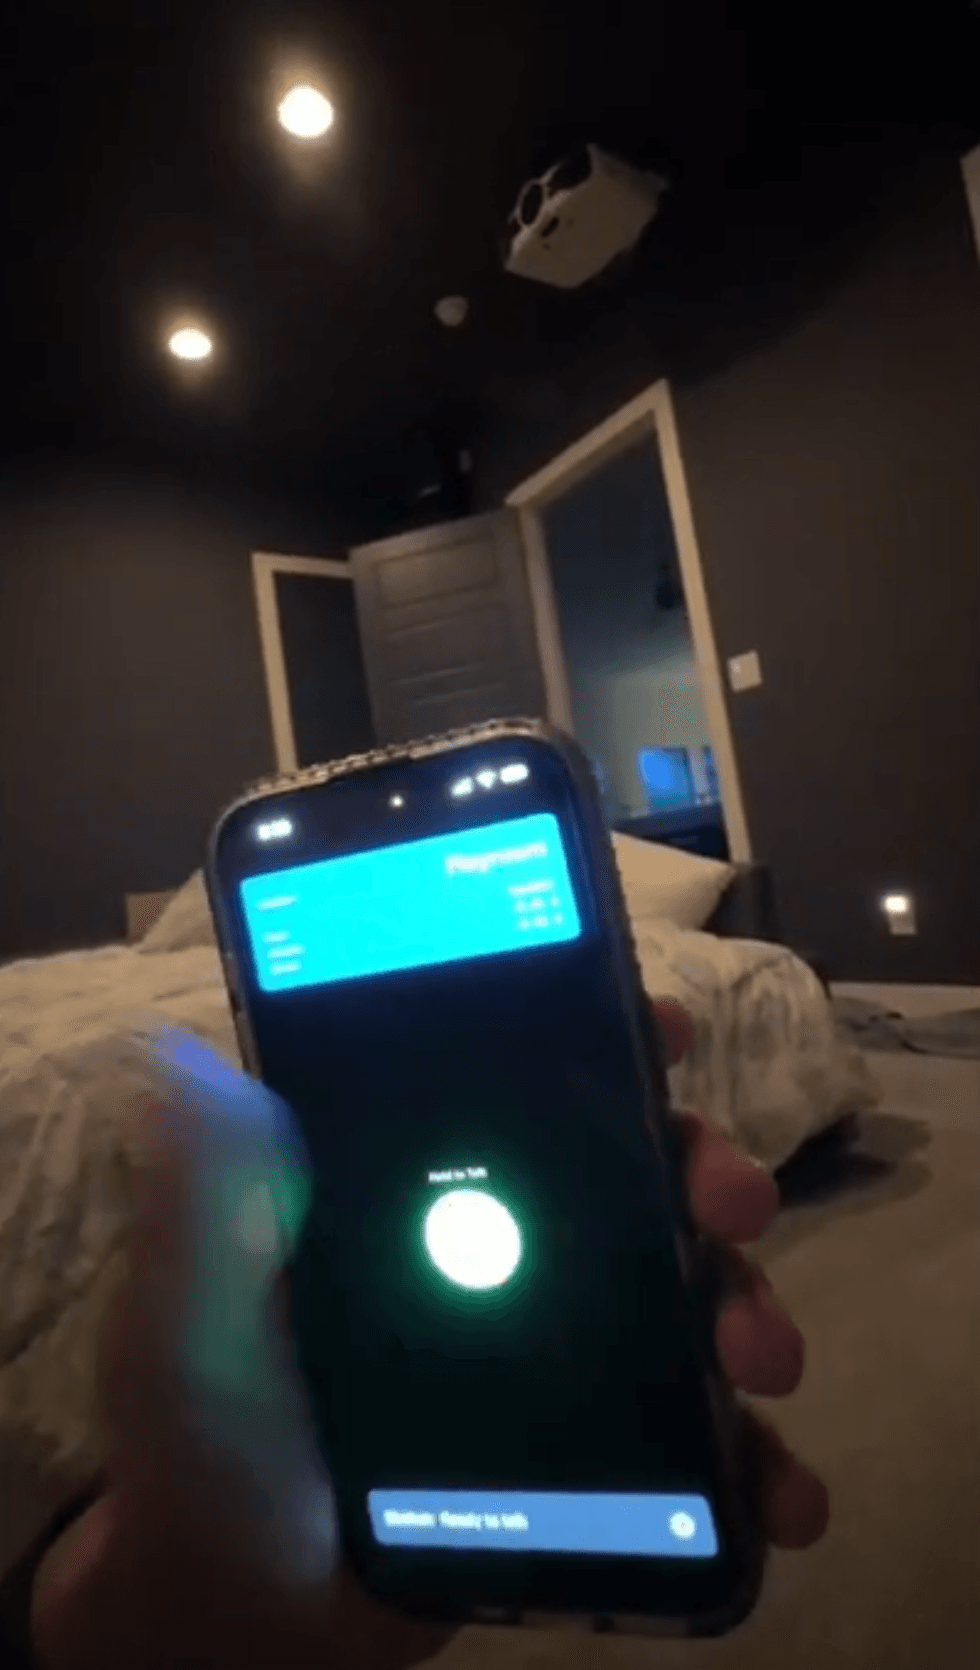
The live-control proof: phone interface up, bedroom lights responding. A friend's note
Showed gapi v1 to a friend. They said, "really built jarvis just for a school project." Took that as the sign v1 wasn't enough — v2 should be proactive, know where I am, see my emails, control music.
Gemi — the v2 idea
Next page of the spiral notebook had a robot labeled Gemini standing between two speakers labeled System Input and User Input. The router fed it from the internet — void, chromecast, macbook, iphone — all running into the same listener.
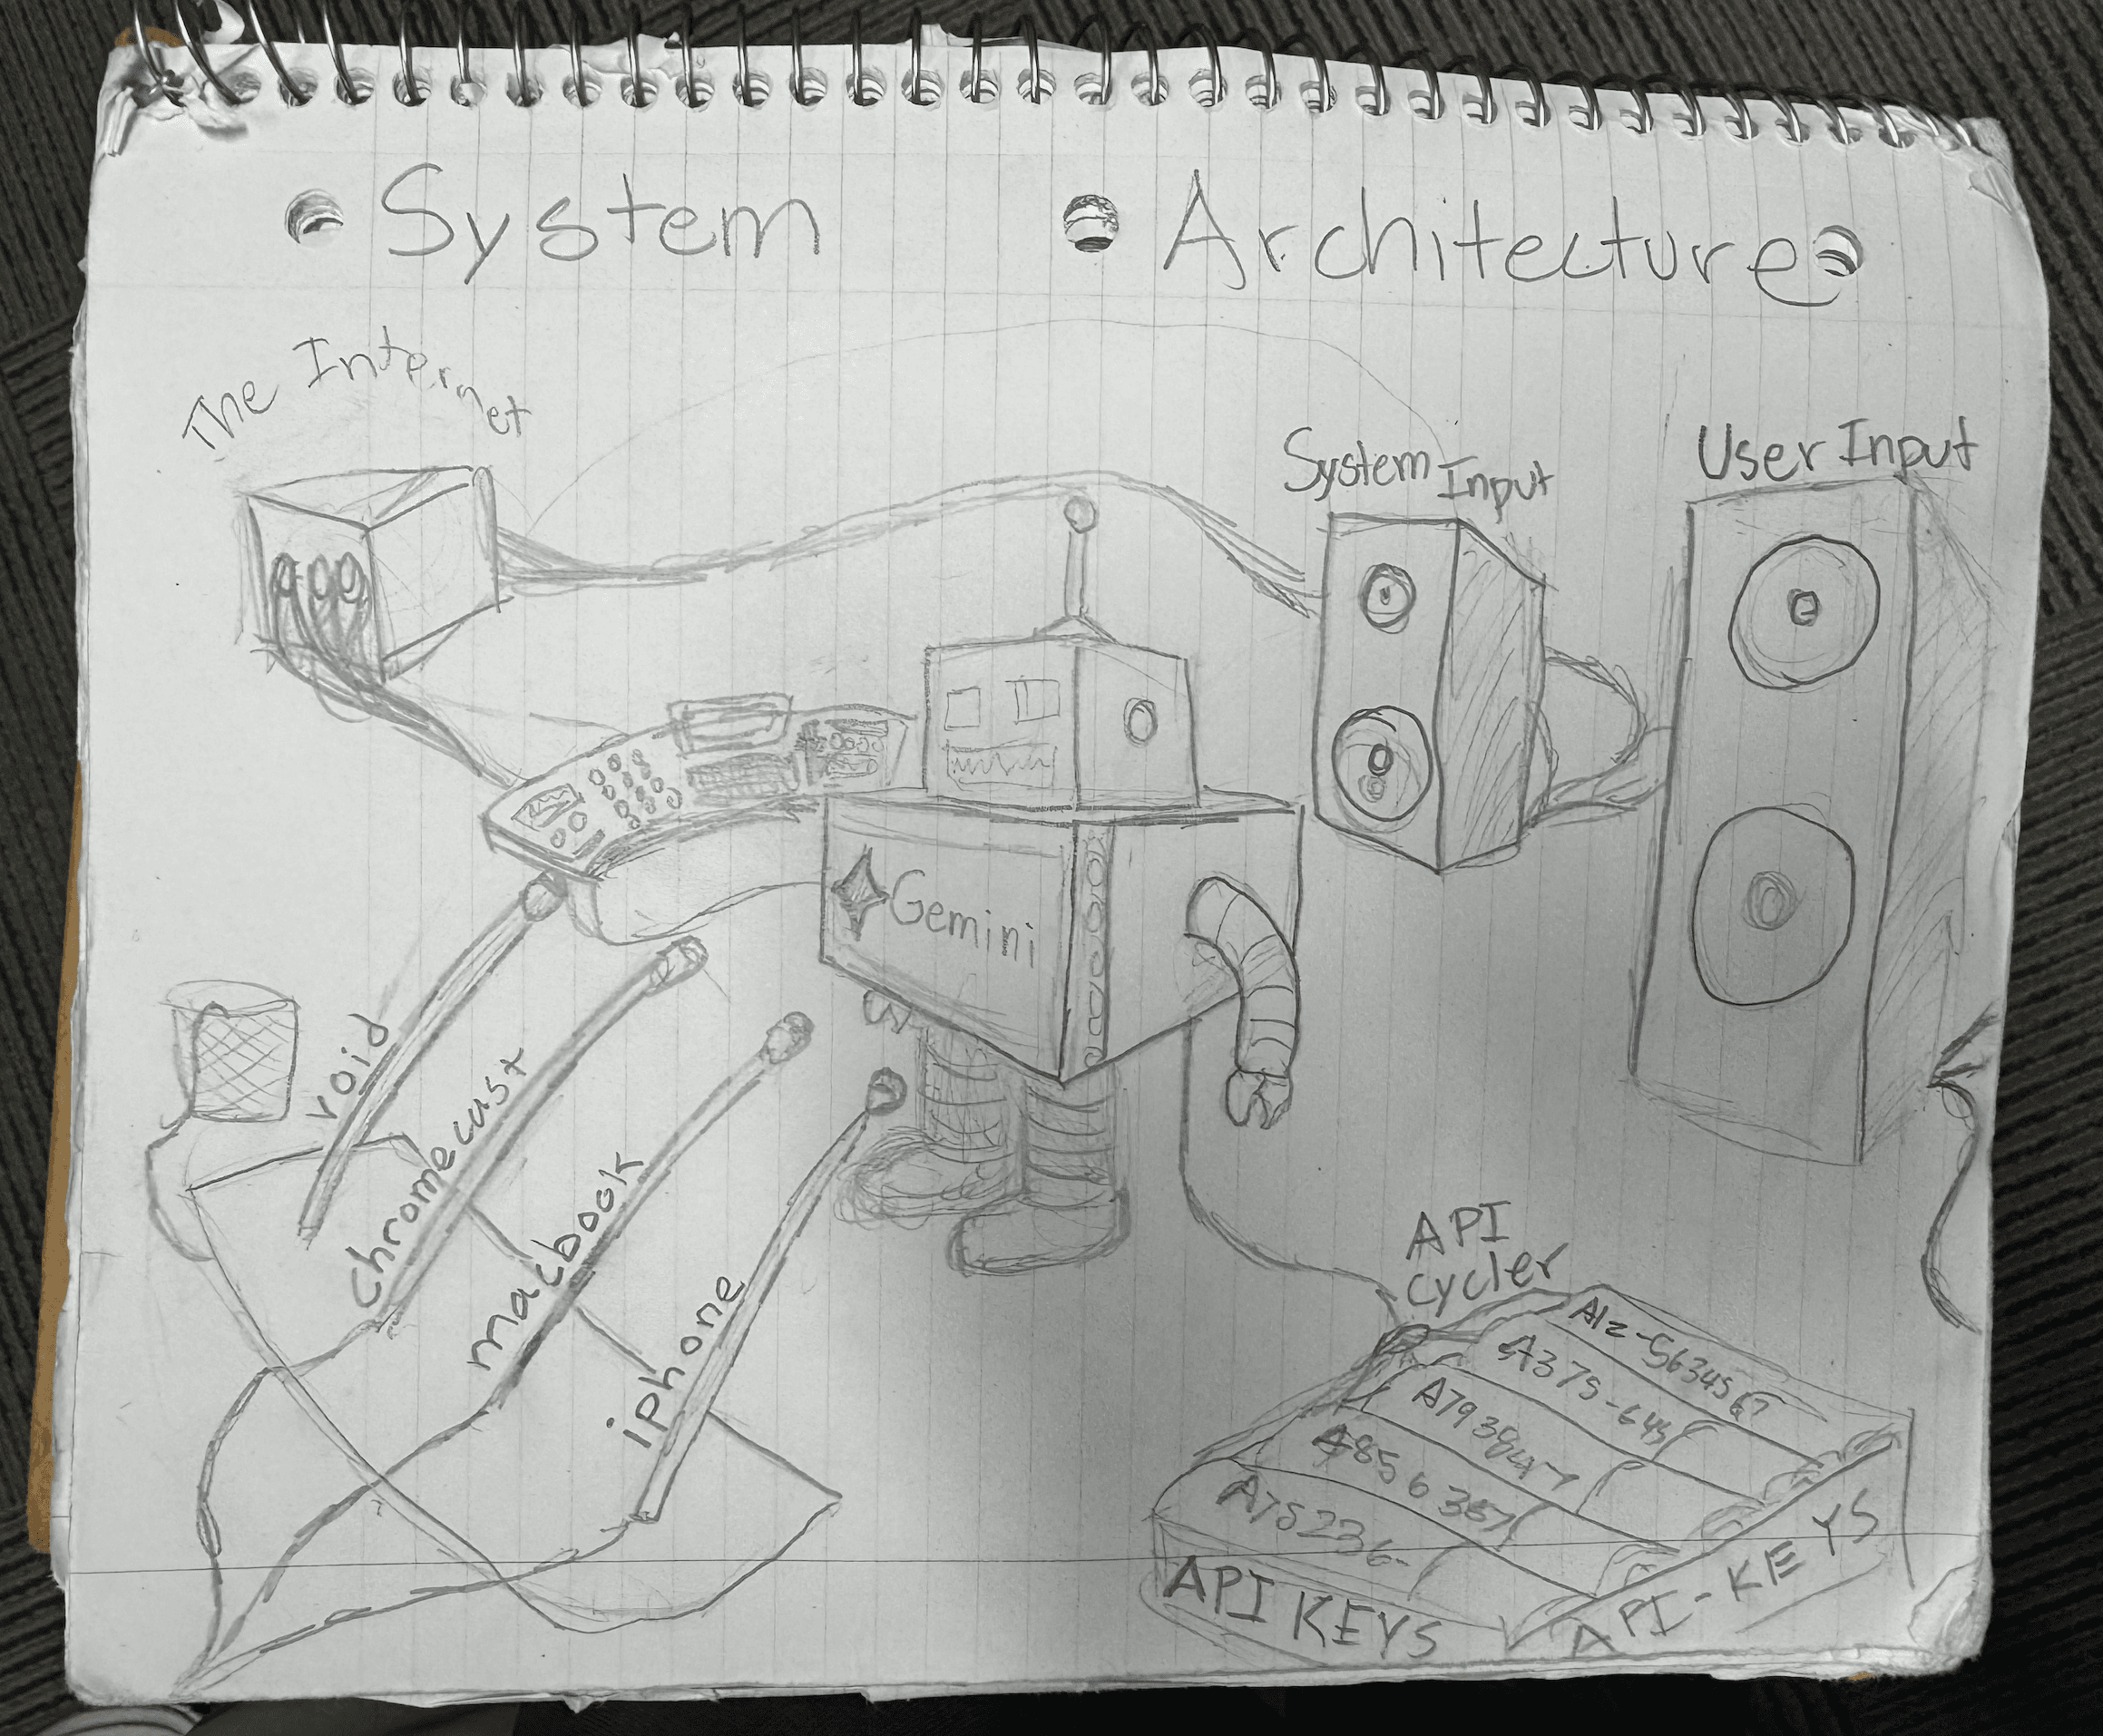
v2, page one: Gemini as the box between system input and user input. Tech stack
Gemini at the center, surrounded by what it had to talk to — Universal Devices for the lights, Google APIs for everything Google, VLC and Google Cast for playback, Scikit-Learn for the presence model, Python on the server side, Swift on the iPad.
Gemini Live
Swapped the v1 STT-LLM-TTS chain for a single WebSocket to the Gemini Live API. Text, audio, and video out; text and audio back. One connection, real-time, no stitching three models together to fake the cadence.
iBeacon dead end
First attempt at presence detection: emit iBeacon advertisements from a Bluetooth card and triangulate from fixed receivers. The card refused to output the format. Spent days on it, never got a frame out.
Random Forest, 99.7%
Switched approaches. An iPhone app logged nearby wireless signal-strength readings, labeled each sample by the room I was standing in (Bedroom, Media, Playroom), and POSTed them to a tiny server. On that four-day dataset, the reported results were RandomForestClassifier 99.7%, KNeighborsClassifier 98.6%, and LinearSVC 98.0%; performance beyond that data was not established. A live prediction came back Playroom 96 / Media 4 / Bedroom 0.
Where it confused itself
In that dataset, the confusion matrix mixed Playroom with Media — the two rooms that share a wall. The wireless signal couldn't tell which side of the drywall I was on, and honestly neither could I half the time.
Gemi — Gemini Smart Home
Closing slide: a Wii console box, repackaged. Same proportions, same white plastic, same translucent play button — relabeled 'Gemi' on the console and 'Gemini Smart Home' on the box. The product the room had quietly become.
Result
Demonstrated room controls for lights and Spotify.
What I learned
Splitting a quick spoken response from Gemini's room-action track meant the assistant could acknowledge me while a light or music command was still being handled. The iPad-as-mirror was the other half: not a screen I had to summon, but a surface on the wall that pulsed when the assistant heard me.